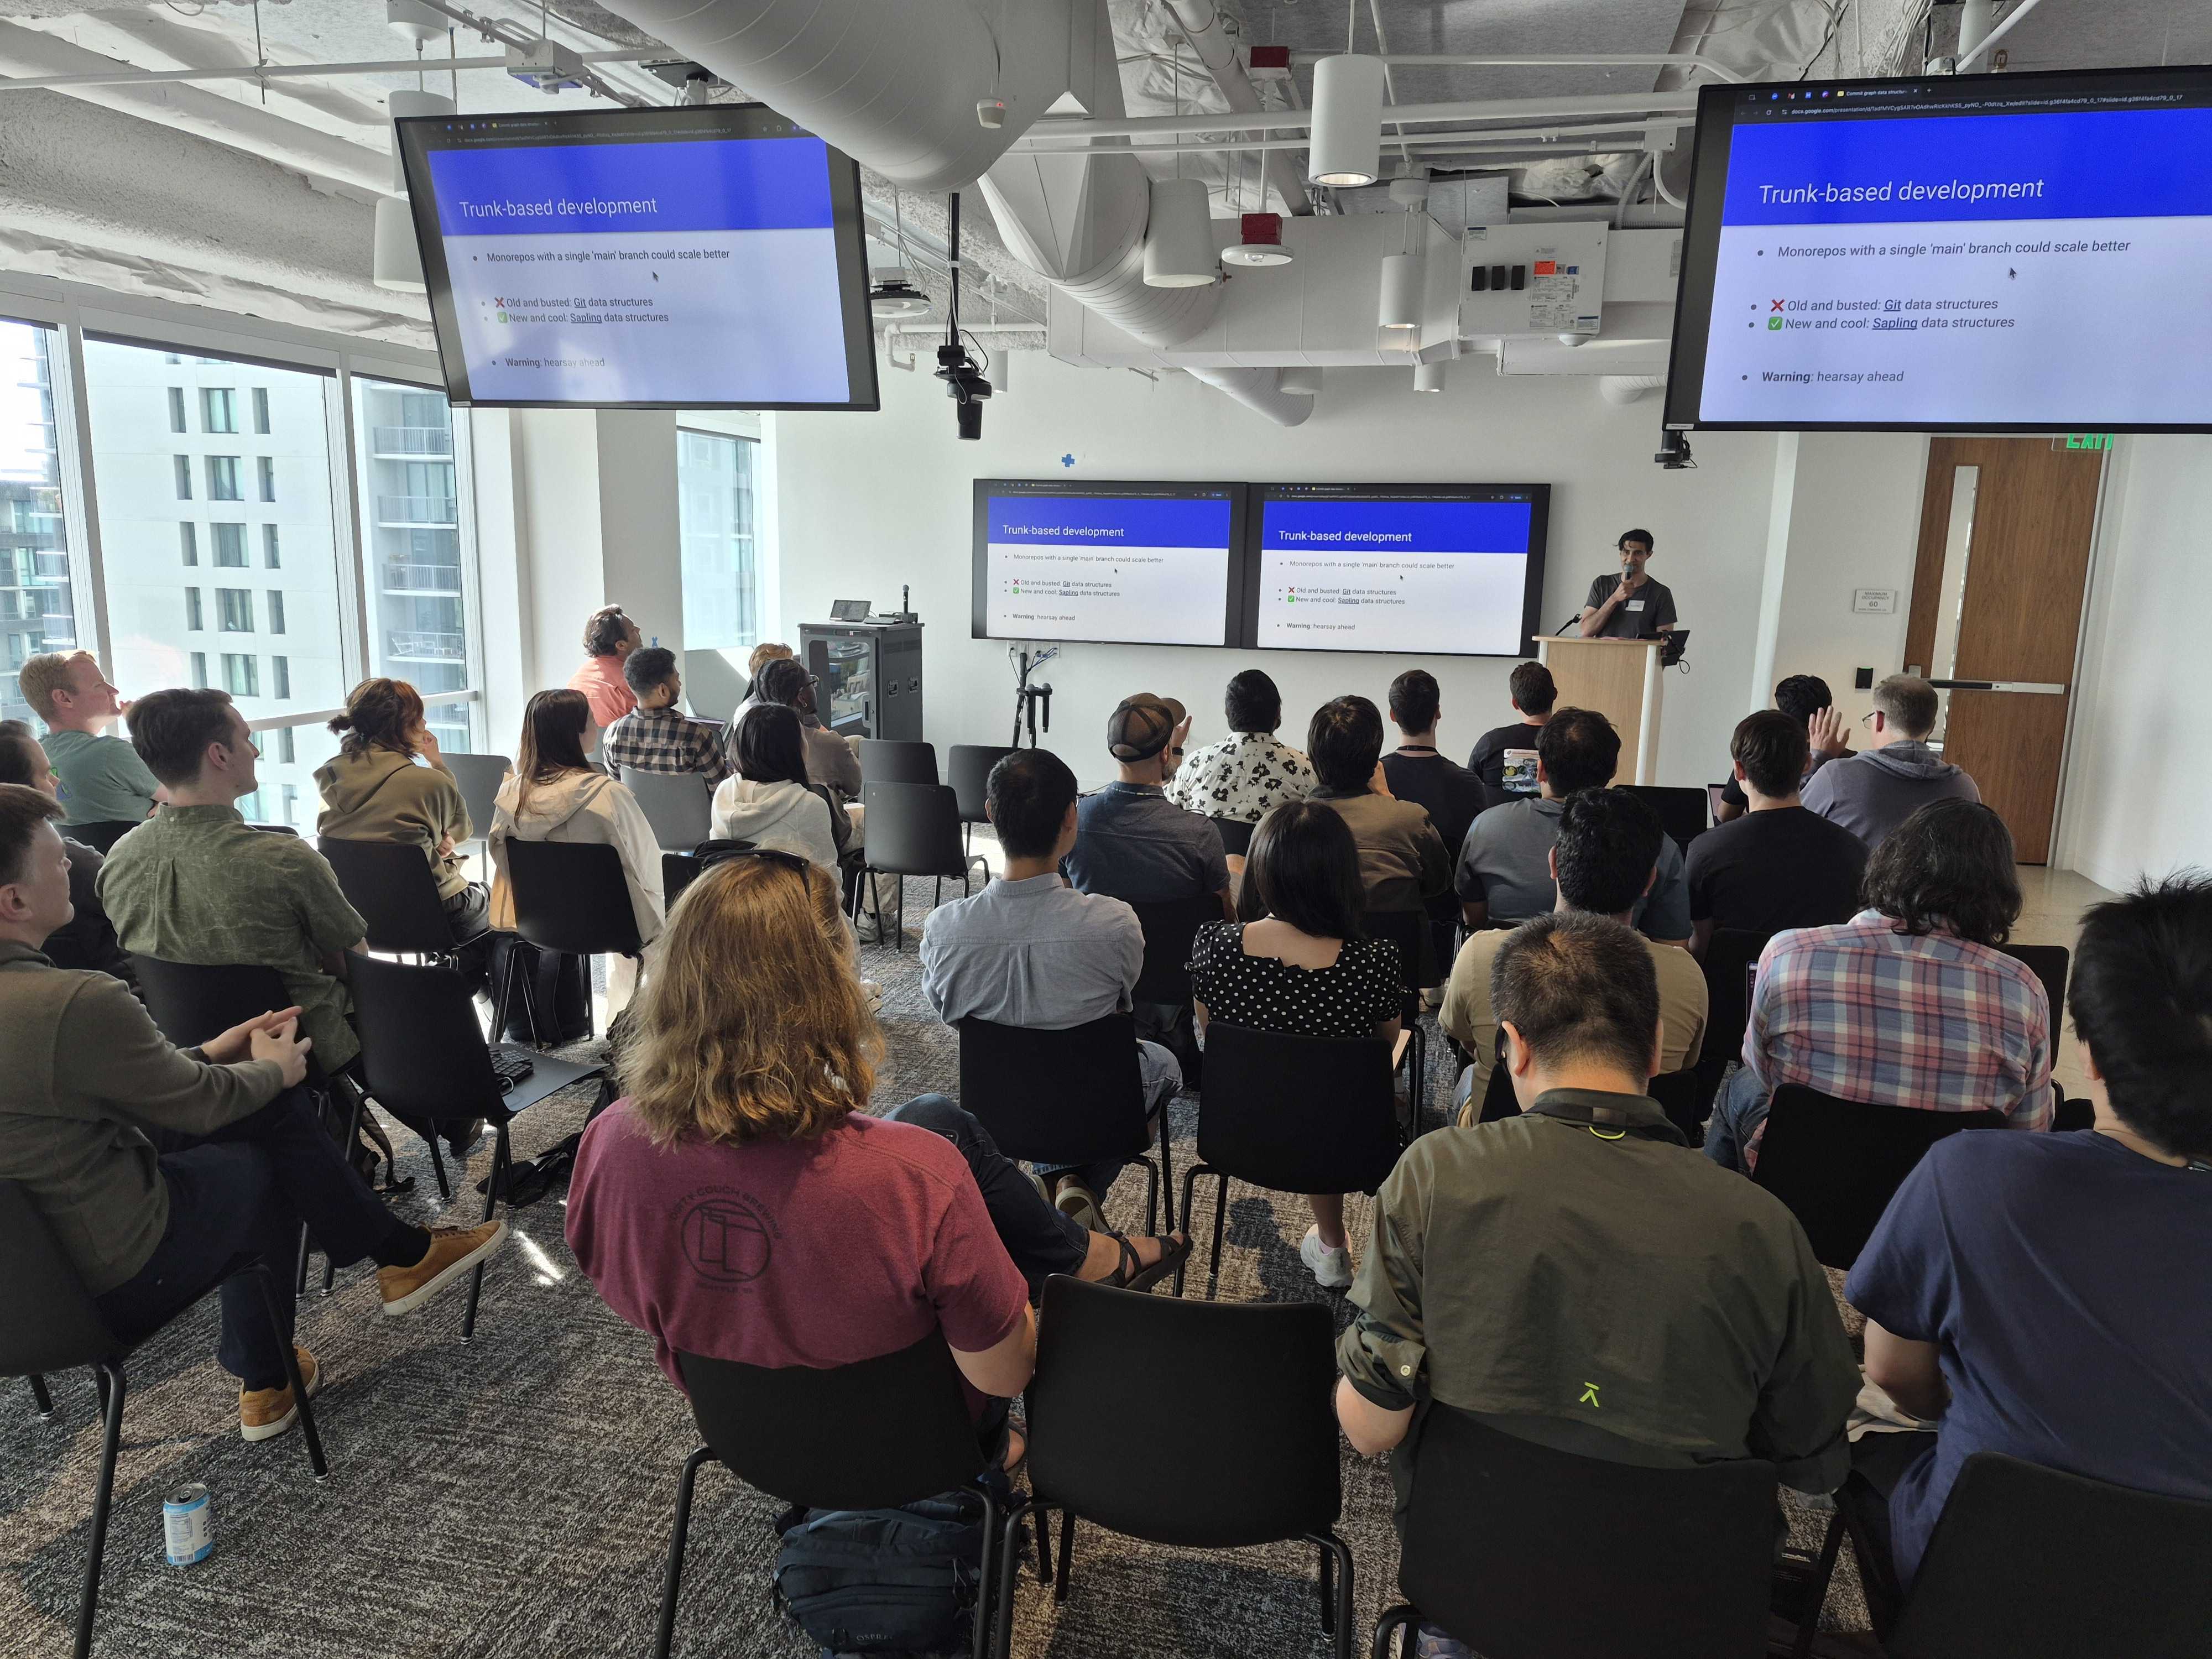
This post is based on my lightning talk at BazelCon 2026. You can watch the talk on YouTube below.
This talk shows how to support new rule sets by writing an extension with Gazelle's new v2 API, which supports better error handling and dependency resolution. We'll also talk about how Gazelle works with extensions, how to support offline indexing, and how to write extensions in languages other than Go.
This post is based on the BazelCon 2026 talk I gave with Antonio Di Stefano
(Frekt.dev). You can watch the recording on YouTube
below.
Bazel has used persistent
workers for years to
make compilation faster. A persistent test runner applies the same idea to
tests: keep a long-running test execution process alive and reuse it across
multiple tests, instead of paying its warmup cost every time.
Amsterdam hosted more than 500 build engineers at BazelCon 2026, and one reality framed nearly every discussion: automated coding tools are hammering developer infrastructure.
When autonomous agents generate thousands of pull requests an hour, local laptops lock up and traditional CI pipelines buckle. Across three days of keynotes, workshops, and late-night hallway debates, our team at EngFlow focused on solving that exact crunch. EngFlow showed up with a large presence, including nine technical talks, four sold-out training tracks, and new open-source projects our engineers brought to the community this year. Plus, we had a full-time barista serving everything from espresso to matcha lattes, and a sold out Extreme Scale Party with our partner VirtusLab.
We’re fond of Bazel, and particularly fond of the capabilities it offers developers. Faster builds, made more efficient through remote execution and caching, made more understandable through declarative configuration, queryability, and precise logging – these deliver benefits and solutions to developers once Bazel’s all set up and integrated into their daily processes.
But it’s a rare developer who enjoys spending their time and effort in build system configuration. Wouldn’t we rather be solving our customers’ problems? And the decision to migrate from an existing build system to Bazel is one that demands consideration of huge trade-offs; the labor and opportunity costs of engineering time spent on migration and adapting internal workflows to a new build system discourage the pursuit of its advantages.
Bazel makes your builds correct and reproducible. Making them fast, and keeping them fast as your codebase and your team grow, is a different problem. It's the very problem that EngFlow was created to solve. Our team spent years on the adoption side of Bazel, helping companies put it into production, contributing and creating Bazel's core features, and the pattern is almost always the same: teams love what Bazel does for correctness, then run straight into what it costs to operate for speed.
Today, that's much easier to reach. EngFlow, the platform that runs the largest managed Bazel fleet in the world, with over 3 billion build and test actions every week for teams like Arm, Databricks, and Canva, is now one install away for every team on Origin. Read more about this in Origins's announcement on X (Twitter) and Linkedin.
EngFlow and Deliveroo (a DoorDash company) recently co-hosted a Build Meetup at Deliveroo's London offices. The event came together thanks to Matt from Deliveroo's engineering management team and Vaibhav from EngFlow, who brought together engineers from Deliveroo, EngFlow, Jane Street, and the local build community.
While talks spanned Bazel, Buck2, and Dune, a central theme emerged: as enterprise codebases grow past tens of millions of lines, the main bottleneck moves from writing code to testing and packaging it.
Here is a breakdown of the three technical presentations from the event.
Back in June I was sitting on a train to Zurich. The plan was to meet colleagues and work together on figuring
out how to migrate CMake projects to Bazel. I was looking forward to chatting with my colleagues in person,
but I was not optimistic about the migration process.
Truth be told, I was expecting to spend the week walking through the problems parsing the custom CMake language
and CMake being Turing complete, maybe even look at a few concrete cases like generated files and configuration
flags, finally conclude it couldn't be done, and return home with not much to show. Oh boy was I wrong.
On July 28, 2026, Uber and EngFlow co-hosted a Build Meetup at Uber’s Seattle office. This wouldn’t have been possible without the help of Sergey Balabanov at Uber, who not only presented one of the talks, but also energetically arranged and helped support this event from the Uber side. Thanks again, Sergey!
And, even though nobody planned a theme for this particular meetup (our meetups are holistically focused on “Build, Scale, Investigate”), one showed up anyway. Code is getting cheaper to produce. Uber put it flatly: “AI is a problem, apparently.” Every talk examined some part of the machinery that turns abundant code into software you can trust. Let’s take a look!
Today, the new https://bazel.build/ website has finally launched. This is the
first step in a larger evolution of Bazel's documentation story. Much of
the content remains the same (the eagle-eyed among you may notice a few new
pages), but this change marks a new era of Bazel documentation.
The Bazel site migration is more than just a fresh coat of paint. One of the
underlying motivations for this change is to empower the Bazel community to make
more changes to Bazel's documentation. Before the migration, Bazel's website was
built on Google documentation infrastructure. While the capabilities of that
infrastructure were largely sufficient for Bazel's needs up to now, the
contribution experience was not.
Today's https://bazel.build/ is built on Mintlify.
With this new platform, each incoming documentation pull request to Bazel is
automatically greeted with a preview. For even faster iteration, you can
build the site
locally. These
improvements eliminate guesswork, and better equip contributors to make changes
to the Bazel docs with confidence.
One of the classic strategies to speed up a system is to avoid redundant work. Scalable build systems like Bazel and Buck2 heavily employ this strategy in various ways, with remote caching and content-addressable storage being two prominent examples. While remote caching prevents repeating redundant build actions, content-addressable storage (CAS) exists for the purpose of data deduplication. However, traditionally CAS operates at the granularity of a single file. When you modify a single byte in a file and store it in a CAS, the CAS stores a second, complete file. Deduplication at the file level is quite palatable for smaller files; a single build invocation typically contains many thousands of small files. Who cares if we store a couple more?
However, as file sizes increase, the cost of storing yet another slightly modified version of a file becomes more expensive. Instead of tossing a couple extra kilobytes into storage, you might be storing a few more gigabytes. Now, consider where these large files come from. These large files are often outputs of build actions, and those build actions depend on many smaller inputs. As those many inputs churn, the outputs also churn. Suddenly the cost of touching a tiny little source file isn’t just the cost of uploading a new version of the source file to CAS–it’s now also the cost of all the large outputs that are produced by the build. This dictates the growth rate of your CAS storage costs, which scales directly with the number of incoming builds. At AI-scale, these costs have become more important than ever before.